PhantomBuster Alternatives for Twitter (X) Data in 2026
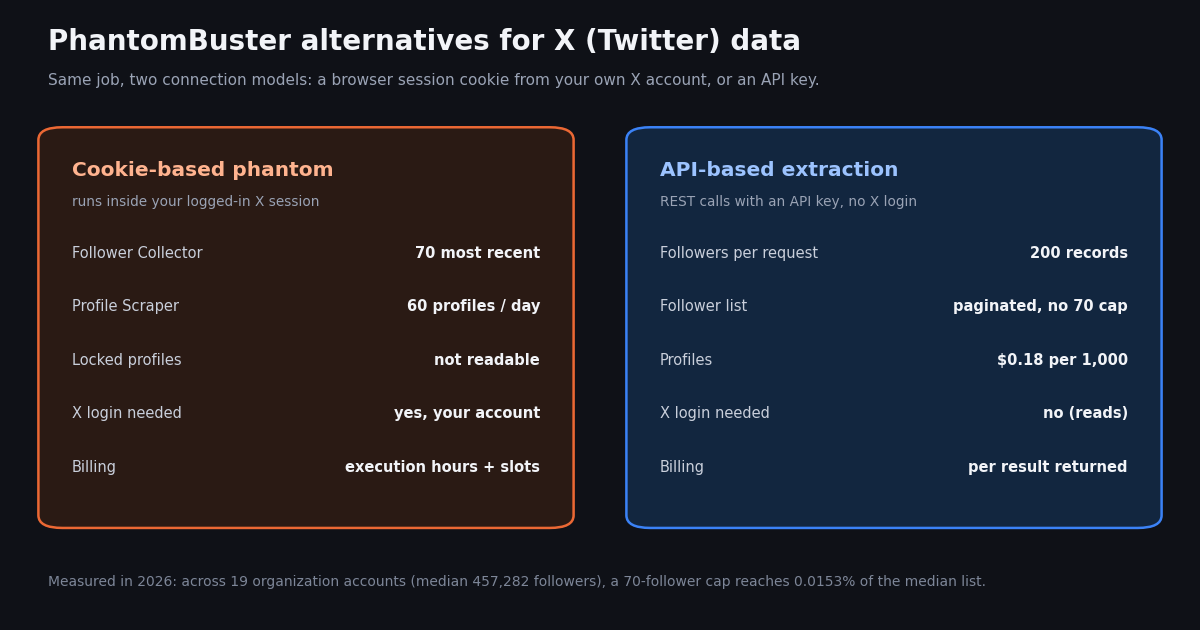
- PhantomBuster's X phantoms run on your own X session cookie. The Follower Collector returns at most the 70 most recent followers per account; the Profile Scraper is advised at 60 profiles a day and cannot read locked profiles.
- Plans (PhantomBuster help center): Start $69 monthly ($56/month billed annually), Grow $159, Scale $439; you buy execution hours and slots, not rows.
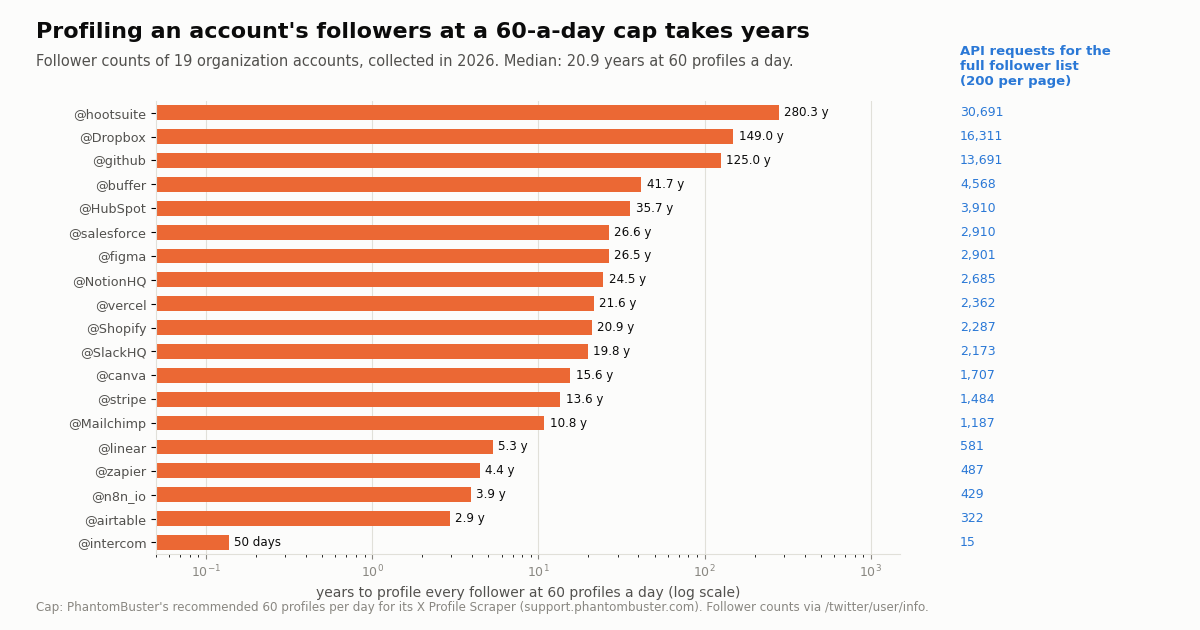
- Measured in 2026: across 19 organization accounts the median follower list is 457,282; a 70 cap reaches 0.0153% of it and 60 profiles a day would need 20.9 years.
- API route:
/twitter/user/followersreturned 1,200 follower records in 6 requests; @zapier's full list of 97,274 would take 487 requests and about $0.97. - Price vs the official X API: $0.15 vs $5 per 1,000 tweets (about 33x), $0.18 vs $10 per 1,000 profiles, on X's pay-per-usage rate card.
- Real chatter: of 80 recent X posts mentioning PhantomBuster, 28.8% were about LinkedIn and 1.2% about X, so most "alternatives" lists answer the LinkedIn question.
PhantomBuster is a cloud automation platform: you pick a ready-made script (a "phantom"), connect your browser session, and let it extract data or perform actions on LinkedIn, Instagram, X and other sites on a schedule. Most "PhantomBuster alternatives" articles are written for LinkedIn prospecting and compare outreach sequencers. This page answers the narrower question for teams that use, or planned to use, PhantomBuster's Twitter (X) phantoms: what those phantoms actually return, what the plans cost, what the session-cookie model means for your account, and which alternatives get the same X data with fewer limits.
The angle here is X data extraction specifically. For a head-to-head on one scraping marketplace see our Apify Twitter scraper alternative comparison; for a broad scraper shortlist see the Twitter scraper comparison; for the follower-export workflow in code see the following-list export tutorial. This page links those instead of repeating them, and adds what they lack: PhantomBuster's own X limits, verified this session from its help center, measured against real follower counts we collected in 2026.
0.0153%
What PhantomBuster's X (Twitter) phantoms do, and their published limits
PhantomBuster's help center lists a family of X phantoms. Extraction phantoms: Follower Collector, Following Collector, Profile Scraper, Tweet Extractor, Search Export, Hashtag Search Export, Tweet Likers Export, Profile Likes Extractor, Media Extractor and Profile URL Finder. Action phantoms: Auto Follow, Auto Unfollow, Auto Liker, Auto Retweeter, Auto Poster and Message Sender. Every one of them takes your X session cookie as an input, connected through PhantomBuster's browser extension or copied by hand, and the help pages add that your X account language must be English (or Polish, French, Japanese or Russian) or the phantom may fail with an "Invalid session cookie" error.
The limits below are quoted from PhantomBuster's own "Automation rate limits" article and the per-phantom help pages (support.phantombuster.com), read this session. PhantomBuster describes them as "a technical account limit only" and notes that X has further, non-public rules against aggressive behavior.
The two caps that matter for data work. The 70-follower ceiling on the Follower Collector is the one most people hit first: the help page says plainly that the phantom "can only extract up to 70 of the most recent followers per account". The 60-profiles-a-day recommendation on the Profile Scraper is the second: enrichment of any real audience becomes a months-long drip.
One inconsistency to know about. For unverified accounts the Tweet Extractor page gives up to 1,000 posts a day, while the rate-limits article gives 5,000. We report both because PhantomBuster publishes both; test with your own account before planning around either.
PhantomBuster plans and what they buy
PhantomBuster's pricing page is a JavaScript app, so the figures below come from its help center article "What Each PhantomBuster Plan Includes", which marks the prices as current for 2026 and excludes VAT. Annual billing takes 20% off.
What the meter counts. PhantomBuster sells time (execution hours) and parallelism (slots), not rows of data. Each X phantom occupies one slot while it is configured. On the free plan, CSV exports keep only the first 10 rows and JSON export is unavailable, per the Follower Collector help page.
Why hours are not the bottleneck for X. At the published speed of about 35 seconds per 2,000 followers, the Start plan's 20 hours could in principle move millions of rows. In practice the per-account caps in the previous section bind long before the hour budget does: 70 followers per account, 60 profiles a day. So the useful question for an X buyer is not "which plan" but "do the caps fit my job".
The session-cookie trade-off: whose account does the work
A session cookie is the credential your browser holds after you log in to X. Handing it to a cloud tool lets that tool act as you: every phantom request is made by your account, from PhantomBuster's servers, inside X's limits for your account. That is why the help pages tie the daily caps to account status (verified, unverified, new) and why they recommend spreading actions across several launches in daytime hours.
What it means in practice. If X rate-limits, locks or suspends the account, every phantom that uses it stops, and the account is yours, not a disposable one. If you log out or X rotates the session, the cookie must be reconnected. The cookie also grants broad access to the account, so it should be handled like a password. X's own automation rules (help.x.com/en/rules-and-policies/x-automation) apply to anything run through your session, whichever tool runs it.
The same is true of self-hosted scrapers. The open-source Python library twscrape (github.com/vladkens/twscrape, MIT license, v0.21.0 released in 2026) states in its README that it "requires authorized X/Twitter accounts" and recommends adding them from browser cookies. Moving from PhantomBuster to a library you host changes who operates the scraper, not the fact that your accounts carry the risk.
What an API key changes. A data API like TwitterAPI.io is called with an API key in an X-API-Key header. Reads (followers, profiles, tweets, search) need no X account and no cookie from you, so there is no personal account to lose when you pull a large follower list. That is the core difference this page is about.
Measured: how far 70 followers and 60 profiles a day go on real accounts
To put the caps against real audiences, we looked up the current follower counts of 19 organization accounts that growth, sales and developer-tool teams commonly study: SaaS, automation, design and commerce brands. Counts ranged from 2,972 to 6,138,042, with a median of 457,282.
The 70-follower cap. Because the Follower Collector only ever returns the 70 most recent followers, it reaches 0.0153% of the median list. For @zapier (97,274 followers) that is 0.072%; for the smallest account in the set, @intercom (2,972), it is 2.3553%. For a list that size the cap is not a sampling choice, it is a snapshot of the last few hours or days of new follows.
The 60-a-day profiling cap. Profiling every follower at 60 a day would take 50 days for @intercom, 4.4 years for @zapier and a median of 20.9 years across the set. The chart puts every account on one log scale next to the number of API requests the same list needs at 200 followers per page.
How to read it. The PhantomBuster column is a ceiling set by the vendor's help center, not a speed we benchmarked; we did not run PhantomBuster. The API column is arithmetic on the page size documented for /twitter/user/followers (200 per page, newest first), which our own pulls matched exactly: 6 requests returned 1,200 records.
What a real follower sample looks like (and what a 70-row export misses)
We then pulled the newest 1,200 followers of three automation and no-code brands (@zapier, @n8n_io and @airtable, 400 each) with /twitter/user/followers, 6 requests in total. The follower records belong to private individuals, so we publish only aggregates; no account in the sample is named or quoted.
Locked profiles. 6.4% of the newest followers were protected. PhantomBuster's Profile Scraper page says data from locked profiles cannot be extracted; a follower list API still returns the public profile fields of a protected account (name, bio, counts, the protected flag), but not its posts.
Empty and new accounts. 13.6% had never posted and 33.2% were under a year old; 40.5% had fewer than 10 followers, and the median follower had 22 followers and 74 posts. The newest followers of any brand skew toward fresh accounts, and a 70-row export is made entirely of the newest followers, so it over-represents exactly this slice. If you are qualifying leads, you want the whole list and a filter, not the last 70 sign-ups.
What this sample cannot show. Three brands and the newest 400 followers each are a snapshot, not the full audience; older followers usually look different. Use the shares as a reason to pull and filter the full list, not as a benchmark for every account.
PhantomBuster alternatives for X data, compared
There are four realistic ways to replace an X phantom. They differ on whose account does the work, how the cost scales, and how much you operate yourself. Competitor URLs are given as plain text.
TwitterAPI.io. A REST API over X data with endpoints that map one to one onto the extraction phantoms: /twitter/user/followers and /twitter/user/followings for the collectors, /twitter/user/info and /twitter/user/batch_info_by_ids for the profile scraper, /twitter/user/last_tweets for the tweet extractor and /twitter/tweet/advanced_search for search and hashtag export. You pay only for the data returned; new accounts that pass the automatic bot check get up to $1 of free credits (at most 100,000 credits, no card, one per person or network, expiring after 31 days), and purchased credits never expire.
Official X API. The sanctioned route, billed per resource on the pay-per-usage rate card at docs.x.com/x-api/getting-started/pricing: $0.005 per post read, $0.010 per user read and $0.010 per follower or following read, capped at 3 million post reads a month before Enterprise. X adds $20 of credits when you save an eligible card and make a first purchase. It needs a developer account and an app.
Self-hosted libraries. twscrape is actively maintained and free, but it runs on X accounts you add from cookies, so the account risk of the cookie model stays with you, plus proxy and maintenance work. Our Twitter scraper comparison covers the open-source options in more depth.
Scraping marketplaces. Apify and similar marketplaces host many third-party X actors with different pricing and reliability. Our Apify Twitter scraper alternative comparison covers that choice in detail, so it is not repeated here.
If your phantom use was LinkedIn. Our post sample below suggests most PhantomBuster conversation is about LinkedIn. LinkedIn outreach tools are a different category with different risks, and this page does not rank them.
Cost of the same X jobs: PhantomBuster caps vs API prices
PhantomBuster's plan price is fixed per month while the API cost scales with rows, so the honest comparison is per job. The API figures below use the published TwitterAPI.io prices and the follower counts we measured; the official X figures use X's pay-per-usage rate card.
How the follower price works. The follower endpoint bills per follower returned and its docs (docs.twitterapi.io) set 1 credit per follower at the maximum page size of 200, rising to 2 or 3 credits on smaller pages; $1 buys 100,000 credits. At page size 200 our 1,200-record pull cost about $0.012.
The 33x figure. For tweets the ratio is $5 / $0.15, about 33x per 1,000 tweets against X's pay-per-usage rate card. For profiles it is $10 / $0.18, about 56x per 1,000.
Rate limits. API accounts run at 0.2 requests per second before the first payment and 20 per second once paid (50 on Scale, 500 on Business, up to 1,000 on request), with no per-account daily cap tied to an X login. Subscription plans (Starter $29, Builder $99, Pro $199, Scale $499, Business $1,499 a month) are listed on the pricing page if you prefer a monthly bill.
What X posts about PhantomBuster say
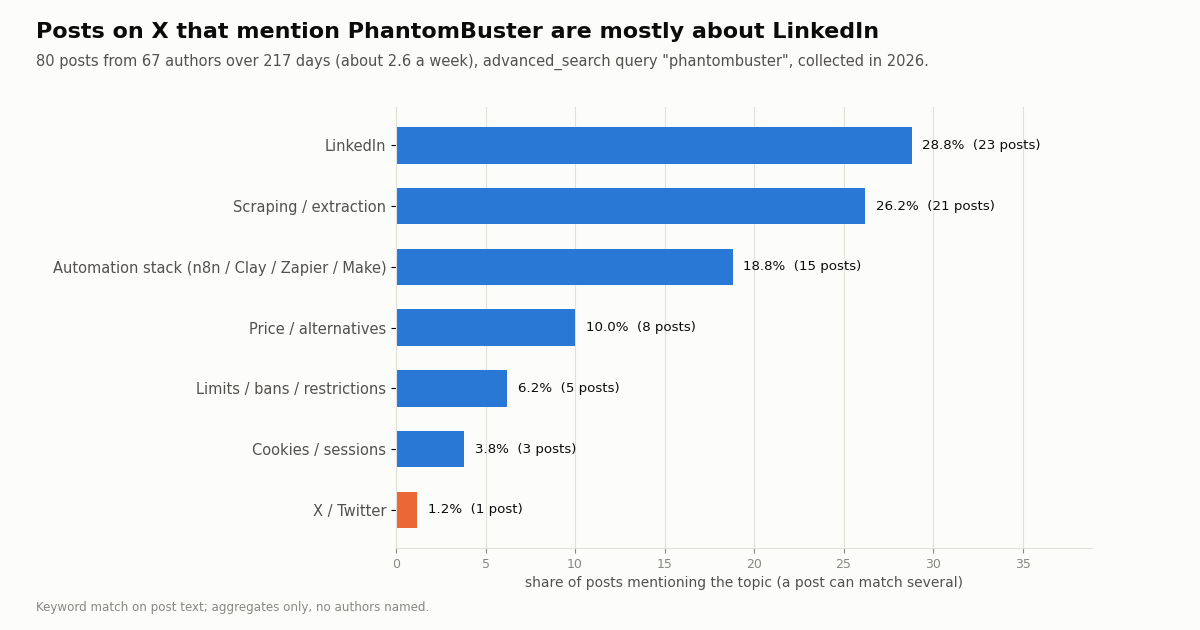
To see why people look for alternatives, we searched X for the word "phantombuster" and kept the 80 most recent posts, from 67 different authors, spanning 217 days (about 2.6 posts a week). We tagged each post by keyword match; a post can carry several tags.
LinkedIn dominates. 28.8% of posts mention LinkedIn and only 1 post mentions X or Twitter, which matches what the top "alternatives" articles cover. Scraping and extraction come next (26.2%), followed by posts that place PhantomBuster in an automation stack with n8n, Clay, Zapier or Make (18.8%).
Volume is low. About 2.6 posts a week is a small sample, and 49 of 80 posts (61%) were in English. Treat the shares as directional. Limits, bans and restrictions came up in 5 posts and cookies or sessions in 3.
Replacing the action phantoms, and how we collected this
Actions are a separate product. PhantomBuster's Auto Follow, Auto Liker, Auto Retweeter and Auto Poster act through your session. TwitterAPI.io also offers write actions through an authenticated session: one /twitter/user_login_v2 login ($0.10, with a proxy you supply) returns login_cookies, and each follow, unfollow, like, retweet or post (/twitter/follow_user_v2, /twitter/like_tweet_v2, /twitter/create_tweet_v2, ...) is then 60 credits, $0.0006, billed per HTTP 200 call. The same caveats apply as with any session tool: the call acts as that account, X can rate-limit, lock or suspend it, the session can need a re-login, and you should use only your own account at a normal human pace under X's automation rules. This is not a way around any limit, and it is not a bulk outreach tool.
How we collected this. Question: how far do PhantomBuster's published X caps go on real audiences, and what do posts about PhantomBuster discuss? Accounts: 19 organization accounts (profiles via /twitter/user/info); follower samples from @zapier, @n8n_io and @airtable (/twitter/user/followers, 2 pages each); search query "phantombuster" (/twitter/tweet/advanced_search, Latest, 5 pages). Window: follower counts and lists as of collection, and the most recent matching posts. Sample: 19 profiles, 1,200 follower records, 80 posts; 33 requests in total, collected in 2026. Our client also looked up the handle @phantombuster; it returned no profile data, so no PhantomBuster account is analyzed here.
What the sample cannot show. We did not run PhantomBuster; its limits are taken from its own help center. The follower shares describe the newest followers of three brands only. Post topics come from keyword matching, not reading intent. Privacy: aggregates only; organization accounts are named, private followers and post authors are not; raw follower and search pages were not kept in the repository.
import csv
import time
import requests

API_KEY = "YOUR_API_KEY"  # from https://twitterapi.io/dashboard
BASE = "https://api.twitterapi.io"
HEADERS = {"X-API-Key": API_KEY}


def all_followers(user_name, max_pages=50):
    """Page through /twitter/user/followers (newest first, 200 per page)."""
    cursor, pages = "", 0
    while pages < max_pages:
        r = requests.get(f"{BASE}/twitter/user/followers",
                         headers=HEADERS,
                         params={"userName": user_name, "cursor": cursor, "pageSize": 200},
                         timeout=30)
        r.raise_for_status()
        body = r.json()
        if body.get("status") == "error":
            raise RuntimeError(body.get("msg"))
        for f in body.get("followers", []):
            yield f
        pages += 1
        if not body.get("has_next_page"):
            break
        cursor = body.get("next_cursor", "")
        time.sleep(0.2)


def recent_tweets(user_name, pages=2):
    """Latest posts of one account via /twitter/user/last_tweets."""
    cursor, out = "", []
    for _ in range(pages):
        r = requests.get(f"{BASE}/twitter/user/last_tweets",
                         headers=HEADERS,
                         params={"userName": user_name, "cursor": cursor},
                         timeout=30)
        r.raise_for_status()
        data = r.json().get("data", {})
        out.extend(data.get("tweets", []))
        if not r.json().get("has_next_page"):
            break
        cursor = r.json().get("next_cursor", "")
    return out


if __name__ == "__main__":
    rows = []
    for f in all_followers("n8n_io", max_pages=5):  # 5 pages = up to 1,000 followers
        rows.append({
            "screen_name": f.get("screen_name"),
            "name": f.get("name"),
            "followers": f.get("followers_count"),
            "following": f.get("following_count"),
            "posts": f.get("statuses_count"),
            "protected": f.get("protected"),
            "created_at": f.get("created_at"),
            "bio": (f.get("description") or "").replace("\n", " "),
        })
    # Keep accounts that look active: posted at least once and not locked
    active = [r for r in rows if (r["posts"] or 0) > 0 and not r["protected"]]
    with open("followers.csv", "w", newline="") as fh:
        w = csv.DictWriter(fh, fieldnames=list(rows[0].keys()) if rows else ["screen_name"])
        w.writeheader()
        w.writerows(active)
    print(f"{len(rows)} followers fetched, {len(active)} active written to followers.csv")
    for t in recent_tweets("n8n_io", pages=1)[:5]:
        print(t["createdAt"], t["likeCount"], t["text"][:80])
Researching this?Free starter credits cover end-to-end testing — Google sign-in, no card. Get a key.
Questions readers ask
What is the best PhantomBuster alternative for Twitter (X)?
It depends on the job. For extracting followers, profiles, tweets or search results, a pay-per-result X data API such as TwitterAPI.io replaces the extraction phantoms without a session cookie and without the 70-follower cap. For the sanctioned route, the official X API bills $0.005 per post read and $0.010 per follower read. For LinkedIn outreach, look at LinkedIn-specific tools; that is a different category.
How many followers can PhantomBuster's Twitter Follower Collector extract?
PhantomBuster's help center says the Follower Collector can only extract up to 70 of the most recent followers per account, and that older followers cannot be collected even across multiple runs. The Following Collector is listed as unlimited.
Does PhantomBuster need my X (Twitter) session cookie?
Yes. Every X phantom takes your X session cookie as an input, connected through PhantomBuster's browser extension or copied manually, and the phantom acts as your account. The help pages also ask that your account language be English or one of four supported languages.
How much does PhantomBuster cost?
Its help center lists Start at $69 monthly ($56/month billed annually), Grow at $159 ($128/month annually) and Scale at $439 ($352/month annually), plus a 14-day free trial and a free plan with 30 minutes of execution time a month. Plans meter execution hours and slots, not rows.
Can I export all followers of a Twitter account without a cookie?
Yes, with a data API. On TwitterAPI.io, /twitter/user/followers takes only the account's userName and your API key, returns 200 followers per page newest first, and pages with next_cursor. The full list of an account with about 97,000 followers is under 500 requests.
Is scraping X with my own account risky?
Any tool that runs on your session acts as you, so X's automation rules apply and X can rate-limit, lock or suspend the account. That holds for cloud phantoms and for self-hosted libraries like twscrape, which its README says requires authorized X accounts. API reads on TwitterAPI.io do not use your X account.
Is twscrape a good free alternative to PhantomBuster?
It is free, MIT-licensed and actively maintained (v0.21.0 released in 2026), but you supply the X accounts and cookies, proxies and upkeep yourself. It moves the operation in-house rather than removing the account dependency.
Continue
- X API pricing (docs.x.com): pay-per-usage rate card, post, user and follower read prices, 3M post-read cap
- TwitterAPI.io docs: Get user followers (page size 200, newest first, per-follower credits)
- twscrape on GitHub: README (requires authorized X accounts, cookie setup), MIT license, releases
- X automation rules (help.x.com)
- TwitterAPI.io documentation: endpoints, authentication with X-API-Key
- Twitter (X) API overview: endpoints and pricing
- Apify Twitter scraper alternative comparison
- Twitter (X) scraper comparison for developers
- Export a Twitter (X) following list via API
- Scrape Twitter (X) data without the official API
- n8n workflow for Twitter (X) data without code
- Free tool: export a Twitter (X) following list
- TwitterAPI.io pay-per-use pricing
- 01Pipedream Pricing in 2026: Connect Plans, Credits and the Workflows Shutdown
- 02Cloudflare Pay per Crawl: How the HTTP 402 Handshake Works, and What It Means for Twitter (X) Data
- 03ScrapingBee Pricing in 2026: Plans, Credit Costs and Alternatives
- 04Firecrawl Pricing: Plans, Credit Costs and What an X (Twitter) URL Costs
- 05LunarCrush API: What It Returns, What It Costs, and When Raw Twitter (X) Data Is the Better Input
- 06Claude Code Alternatives: Seven Coding Agents Checked for License, Free Use and MCP (Twitter/X Data Included)
- 07Bright Data Alternatives for Twitter (X) Data: Prices, Fit and a Measured Cost Test
- 08Replit alternatives in 2026: free tiers, prices, hosting and what X users switch to
Writing about something you built with TwitterAPI.io? Our community rewards program pays API credits for honest tutorials, build logs and videos.
Stop reading. Start building.
Starter credits cover real testing on real data. Google sign-in, no card, no application queue.
Get an API keyAlready building with TwitterAPI.io? Publish an honest tutorial or build log about it and earn up to $200 a month in API credits.