How to Embed Tweets on Your Website — 3 Methods, Measured
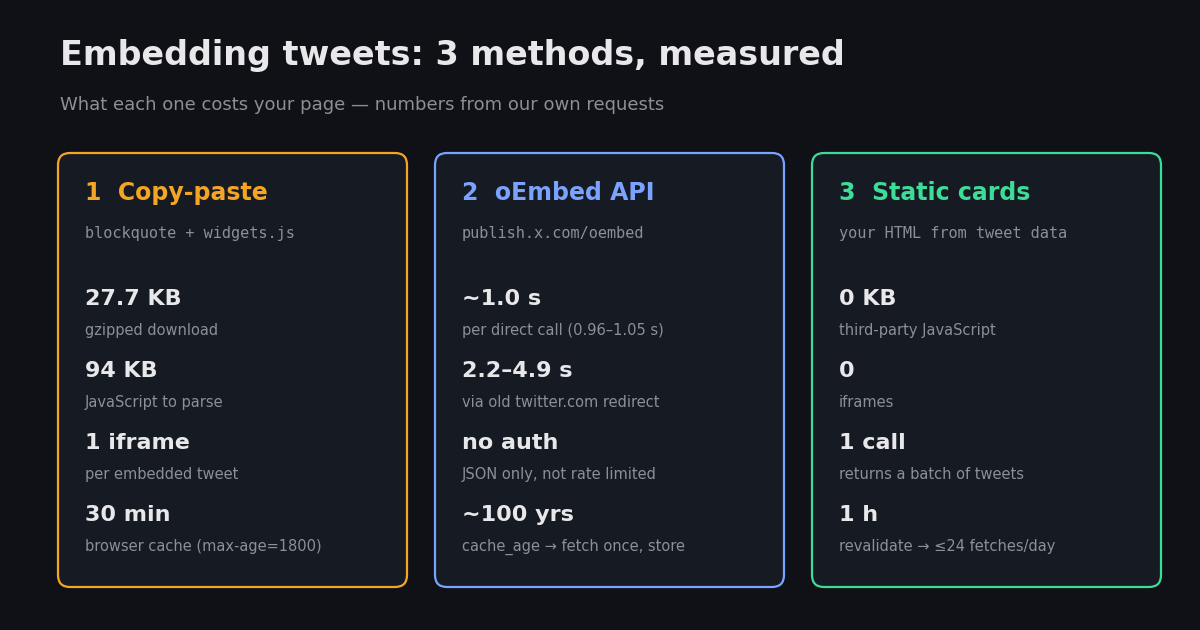
- Copy-paste: share menu → Embed post, or publish.x.com — a
blockquote+widgets.js - oEmbed API:
GET https://publish.x.com/oembed?url=…— free, no auth, cache thehtmlfield - Static cards: fetch tweet data via API, render your own HTML — zero third-party JS
- Measured:
widgets.js= 27.7 KB gzipped / 94 KB raw,max-age=1800(30 min) - Always pass tweet IDs as strings in JavaScript — they exceed
Number.MAX_SAFE_INTEGER - Timelines: only Profile and List timelines survive; Likes, Collections and Moments were retired
Every guide to embedding tweets shows the same thing: click the three dots, choose Embed post, paste the snippet. That works, and for a single tweet in a blog post it is the right answer. It stops being the right answer the moment you embed twenty tweets on a landing page, care about Core Web Vitals, run a strict cookie-consent setup, or want the tweet to match your design system.
This guide covers all three ways to embed tweets on a website — the copy-paste embed, the oEmbed API, and static tweet cards rendered from API data — with numbers we measured ourselves (script payload, cache headers, endpoint latency) and runnable code for each. It finishes with a decision table so you can pick the method that fits your page instead of the one that is easiest to explain.
27,731 bytes gzip · 30-min cache
Method 1 — Copy-paste the embed code (no code, one tweet)
On x.com, open the tweet, click the share icon or the three-dot menu, and choose Embed post. That opens publish.x.com with the tweet URL pre-filled. You can also paste any tweet URL into publish.x.com directly. Adjust the options (dark theme, hide the parent tweet in a reply, language) and copy the snippet.
What you paste is a plain <blockquote class="twitter-tweet"> holding the tweet text, author and permalink, followed by <script async src="https://platform.twitter.com/widgets.js">. The blockquote is the fallback: if the script is blocked by an ad blocker or consent manager, readers still see the tweet as a quote with a link. When the script runs, it swaps each blockquote for an iframe-rendered card with media, counts and the X branding.
In a CMS: many content platforms auto-embed a tweet URL pasted on its own line by calling the oEmbed endpoint described below — WordPress's Embed block is the best-known example. Check your platform's embed settings before pasting raw HTML.
Where it breaks down: every page that uses the snippet pays for widgets.js, and if you paste the snippet five times you get five <script> tags (the browser dedupes the download, but the HTML gets messy). The card height is unknown until the iframe renders, so content below it jumps — a layout-shift (CLS) cost. And you cannot style the card beyond theme and width.
What widgets.js actually costs — measured
Most embed tutorials never say what the script weighs. We fetched https://platform.twitter.com/widgets.js (the official platform.x.com/widgets.js URL redirects there) and read the response headers:
The script itself is modest. The real cost is what happens next: an iframe per tweet, each fetching its own HTML, CSS and images, plus a logging beacon. A page with one embed barely notices. A testimonial wall with thirty tweets can add a lot of network requests and main-thread work, and every card resizes when it finishes loading.
Mitigations if you stay on widgets.js: load the script once per page (pass omit_script=1 in oEmbed and add one script tag yourself), lazy-load it only when a tweet scrolls into view, reserve vertical space with a min-height on the container to reduce layout shift, and add data-dnt="true" to opt the embed out of personalization.
Method 2 — The oEmbed API (free, server-side, cacheable)
The oEmbed endpoint is how CMSs auto-embed tweets, and you can call it yourself: GET https://publish.x.com/oembed?url=<tweet-url>. X's oEmbed documentation lists it as JSON only, no authentication required, not rate limited. The old publish.twitter.com/oembed host still works but answers with a 301 redirect to publish.x.com first.
We timed it: three direct calls to publish.x.com/oembed took 0.96–1.05 seconds each; the same call through the publish.twitter.com redirect took 2.2–4.9 seconds. Either way it is far too slow to call on every page view, which is exactly why the response tells you to cache it.
The parameters worth knowing for single tweets: maxwidth (220–550 px, default 325), hide_media, hide_thread (drops the collapsed parent tweet on replies, which makes height more predictable), omit_script, align, lang, theme (light or dark) and dnt. X explicitly does not support maxheight for tweets and always returns height: null — tweets are text and have no fixed height.
Here is the real response for the first tweet ever posted (omit_script=true):
{"url":"https://x.com/jack/status/20", "author_name":"jack", "author_url":"https://x.com/jack", "html":"<blockquote class=\"twitter-tweet\">…just setting up my twttr…</blockquote>", "width":550, "height":null, "type":"rich", "cache_age":"3153600000", "provider_name":"X", "version":"1.0"}
cache_age is 3,153,600,000 seconds — about 100 years. In practice that means: fetch once, store the html field in your database next to the tweet URL, and never call the endpoint again for that tweet unless you change options. The snippet below does exactly that with a file cache.
# pip install requests
# Server-side oEmbed with a cache: one network call per tweet, ever (until you purge).
import json, pathlib, requests
CACHE = pathlib.Path(".oembed_cache")
CACHE.mkdir(exist_ok=True)
def embed_html(tweet_url: str, theme: str = "light") -> str:
key = CACHE / (tweet_url.rstrip("/").split("/")[-1] + f"_{theme}.json")
if key.exists():
return json.loads(key.read_text())["html"]
r = requests.get(
"https://publish.x.com/oembed", # call x.com directly; twitter.com adds a 301 hop
params={
"url": tweet_url,
"omit_script": "1", # we load widgets.js once per page, not once per tweet
"dnt": "true", # opt the embed out of personalization
"theme": theme,
"hide_thread": "1", # predictable height for reply tweets
},
timeout=10,
)
r.raise_for_status()
data = r.json() # keys: html, author_name, author_url, width, cache_age, ...
key.write_text(json.dumps(data))
return data["html"]
print(embed_html("https://x.com/jack/status/20"))
# <blockquote class="twitter-tweet" data-dnt="true"><p lang="en" dir="ltr">just setting up my twttr</p>
# — jack (@jack) <a href="https://x.com/jack/status/20?ref_src=twsrc%5Etfw">March 21, 2006</a></blockquote>
Lazy-load embeds with twttr.widgets.createTweet
If you want X's own rendering but not its upfront cost, skip the blockquote markup entirely and create embeds from JavaScript only when they are about to be seen. The X for Websites JavaScript API exposes twttr.widgets.createTweet(tweetId, targetElement, options), which returns a Promise that resolves once the iframe is in place. Options include conversation (none hides the parent tweet), cards (hidden suppresses link previews), theme, width, align, lang and dnt.
Pass the tweet ID as a string. Tweet IDs are 64-bit integers; JavaScript numbers lose precision above 2^53, so 463440424141459456 written as a number silently becomes a different ID and the embed fails. Store IDs as strings end to end.
For single-page apps: after a client-side route change, new blockquotes are not scanned automatically. Call twttr.widgets.load(container) on the new content, or use createTweet as below, which sidesteps the scan.
The pattern below loads widgets.js only when the first tweet slot comes within 400 px of the viewport, then renders each tweet as it approaches. Pages that never scroll to the tweets never download the script.
<!-- One widgets.js per page, loaded only when a tweet scrolls near the viewport -->
<div class="tweet-slot" data-tweet-id="20"></div>
<div class="tweet-slot" data-tweet-id="463440424141459456"></div>

<script>
  let widgetsReady = null;
  function loadWidgets() {
    if (widgetsReady) return widgetsReady;
    widgetsReady = new Promise((resolve) => {
      window.twttr = window.twttr || { _e: [], ready(f) { this._e.push(f); } };
      const s = document.createElement("script");
      s.src = "https://platform.twitter.com/widgets.js";
      s.async = true;
      document.head.appendChild(s);
      window.twttr.ready(resolve);
    });
    return widgetsReady;
  }

  const io = new IntersectionObserver((entries) => {
    entries.forEach(async (entry) => {
      if (!entry.isIntersecting) return;
      io.unobserve(entry.target);
      const twttr = await loadWidgets();
      // Tweet IDs MUST be strings: they exceed Number.MAX_SAFE_INTEGER.
      await twttr.widgets.createTweet(entry.target.dataset.tweetId, entry.target, {
        dnt: true,
        conversation: "none",
        theme: document.documentElement.classList.contains("dark") ? "dark" : "light",
      });
    });
  }, { rootMargin: "400px" });

  document.querySelectorAll(".tweet-slot").forEach((el) => io.observe(el));
</script>
Method 3 — Static tweet cards with zero third-party JavaScript
The fastest embed is one that is not an embed. Fetch the tweet's data on your server, render a normal HTML card with your own CSS, and link back to the original. No iframe, no external script, no layout shift (you know the content at render time), no third-party cookies, and the card matches your design system. Vercel's open-source react-tweet library popularized this approach for React; its README describes rendering tweets statically with no iframe and no extra client-side JavaScript.
You need the tweet's text, author, avatar and counts. react-tweet reads an undocumented syndication endpoint that its own docs warn can rate-limit server IPs. A documented API is more dependable for production. With TwitterAPI.io, one GET /twitter/tweets?tweet_ids=<id1>,<id2>,… call returns full tweet objects — text, author (name, userName, profilePicture, isBlueVerified), likeCount, retweetCount, replyCount, quoteCount, viewCount, createdAt, entities and quoted/retweeted tweets — for a batch of IDs.
Follow X's display requirements. X's developer terms include display requirements for showing posts outside its apps: the author's profile picture, display name and @username must be shown and link to their X profile, the post text must appear unaltered below the author, and the timestamp must not be dropped. The snippet below keeps avatar, name and handle linked to the profile, the verbatim text, and the timestamp linked to the post's permalink.
# pip install requests
# Static tweet cards: fetch tweet data in one batch call, render your own HTML.
# Zero third-party JavaScript on the page; you control layout, caching and CLS.
import html, os, requests

API_KEY = os.environ["TWITTERAPI_IO_KEY"]

def fetch_tweets(ids: list[str]) -> list[dict]:
    r = requests.get(
        "https://api.twitterapi.io/twitter/tweets",
        params={"tweet_ids": ",".join(ids)},
        headers={"X-API-Key": API_KEY},
        timeout=15,
    )
    r.raise_for_status()
    return r.json().get("tweets", [])

def tweet_card(t: dict) -> str:
    a = t["author"]
    return f"""
<figure class="tweet-card">
  <figcaption>
    <a href="https://x.com/{a['userName']}">
      <img src="{html.escape(a['profilePicture'])}" alt="" width="40" height="40" loading="lazy">
      {html.escape(a['name'])} <span>@{a['userName']}</span>
    </a>
  </figcaption>
  <blockquote lang="{t.get('lang', 'en')}">{html.escape(t['text'])}</blockquote>
  <footer>
    <a href="{t['url']}"><time>{html.escape(t['createdAt'])}</time></a>
    · {t['likeCount']:,} likes · {t['retweetCount']:,} reposts · {t['replyCount']:,} replies
  </footer>
</figure>"""

if __name__ == "__main__":
    ids = ["20", "463440424141459456"]
    cards = "\n".join(tweet_card(t) for t in fetch_tweets(ids))
    with open("tweets.html", "w") as f:
        f.write(cards)
    print(f"wrote {len(ids)} cards -> tweets.html")
    # Cost: twitterapi.io bills 15 credits per tweet ID requested (missing IDs still billed) -> $0.0003 for these 2.
Static cards in Next.js or React (server-rendered, cached hourly)
In a framework with server rendering, the static approach is a few lines. The component below runs on the server, fetches a batch of tweets with a one-hour revalidation window, and ships plain HTML to the browser. Counts stay roughly fresh without a request per page view: with revalidate: 3600, a page that embeds 20 tweets costs at most 24 batch fetches a day no matter how much traffic it gets.
Keep the API key in a server-only environment variable (never a NEXT_PUBLIC_ one), and lazy-load avatars with explicit width and height so they cannot shift layout. For the React-specific decision between react-tweet, widgets.js and a hand-written component, including what each one fails to render, see our guide to rendering Twitter (X) posts in React.
// app/components/TweetCard.tsx -- Next.js server component, rebuilt at most hourly.
// Renders on the server; ships zero JavaScript for the embed itself.
type Tweet = {
  id: string; url: string; text: string; createdAt: string; likeCount: number; retweetCount: number;
  author: { name: string; userName: string; profilePicture: string };
};

async function getTweets(ids: string[]): Promise<Tweet[]> {
  const res = await fetch(
    `https://api.twitterapi.io/twitter/tweets?tweet_ids=${ids.join(",")}`,
    { headers: { "X-API-Key": process.env.TWITTERAPI_IO_KEY! }, next: { revalidate: 3600 } },
  );
  if (!res.ok) return [];
  return (await res.json()).tweets ?? [];
}

export default async function TweetCards({ ids }: { ids: string[] }) {
  const tweets = await getTweets(ids);
  return tweets.map((t) => (
    <figure key={t.id} className="tweet-card">
      <figcaption>
        <a href={`https://x.com/${t.author.userName}`}>
          <img src={t.author.profilePicture} alt="" width={40} height={40} />
          {t.author.name} @{t.author.userName}
        </a>
      </figcaption>
      <blockquote>{t.text}</blockquote>
      <footer>
        <a href={t.url}><time>{t.createdAt}</time></a> · {t.likeCount.toLocaleString()} likes
      </footer>
    </figure>
  ));
}
Embedding a timeline (profile or list feed)
To show a live feed instead of single tweets, X supports two embedded timeline types: Profile (latest posts from one public account) and List (latest posts from a public list). Likes, Collections and Moments timelines were retired on January 13, 2023, per X's timeline documentation, so older tutorials that show them no longer work.
Generate the code at publish.x.com by pasting a profile or list URL; you get an <a class="twitter-timeline" href="https://x.com/XDevelopers"> anchor plus widgets.js. Size it with data-width / data-height, cap the number of posts with data-tweet-limit (1–20), and strip the frame with data-chrome="noheader nofooter noborders transparent". If you hide the header, X's docs say you must add your own attribution and link to the source timeline.
Reliability caveat: timeline embeds load posts through X's logged-out syndication service. In our own checks from a single IP, the profile-timeline endpoint returned HTTP 429 (rate limited) on some requests and HTTP 200 on others within the same day, and community reports describe blank timelines too. Treat embedded timelines as best-effort. If the feed matters to the page — a status page or a product-update wall — fetch the account's latest posts on your server (TwitterAPI.io GET /twitter/user/last_tweets?userName=<handle> returns up to 20 per page) and render static cards on a schedule.
Embedded timeline not working? The 3 current causes and the durable fix
If your embedded X timeline shows a blank box, a "Rate limit exceeded" message or only the fallback link, the cause is almost always on X's side, not in your snippet: the syndication request that feeds the widget is being refused with HTTP 429, the widget's own script is throwing a render error, or the visitor's blocker or signed-out state changes what loads. X's developer forum has open reports of all three, and the official generator at publish.x.com reproduces the first two. You cannot fix X's widget from your page; you can diagnose which one you are hitting in two minutes, and if the feed matters, stop depending on the widget by rendering the posts yourself.
Cause 1: syndication.twitter.com returns HTTP 429. A profile timeline loads from syndication.twitter.com/srv/timeline-profile/screen-name/<handle>. In a developer-forum thread titled "Embedded Timeline returns HTTP 429 for some users (syndication.twitter.com)", a site owner who sends one request per tab open reports that some visitors get 429 with x-rate-limit-limit: 30 and x-rate-limit-remaining: 0 while others see the feed; at the time of writing that thread has no reply from X. A separate List-timeline thread with the same 429 closed automatically 14 days after its last post, with another developer adding that remaining was always zero and the reset always a few minutes ahead, even on X's own Publish page with @XDevelopers.
What we measured. From one test machine we sent 15 unauthenticated requests to that endpoint (3 each for @XDevelopers, @NASA, @github, @vercel and @nytimes, 3 seconds apart, collected in 2026). All 15 returned 429 with x-rate-limit-limit: 30 and x-rate-limit-remaining: 0, and the reset time was the same for all five accounts, which is consistent with a limit counted per client (IP or network), not per account. That explains the "works for some visitors, not others" pattern: people behind a busy shared network (an office, a carrier NAT, a VPN) can exhaust the bucket before your page asks. The same five accounts each returned a full page of 20 posts from TwitterAPI.io's GET /twitter/user/last_tweets in the same run.
Cause 2: the widget crashes with hydrateRoot is not a function. In the thread "Embedded X Timeline fails to render on X Publish (hydrateRoot is not a function)", a developer shows that when the syndication call does return 200, the timeline stays blank and the console logs TypeError: o.default.hydrateRoot is not a function from a platform.twitter.com/_next/static/chunks/modules-*.js chunk, reproducible on publish.x.com itself. X staff replied that they were checking with the team and would follow up; the thread then closed automatically 14 days later with no fix posted. Nothing in your markup can work around an exception inside X's iframe.
Cause 3: blockers and signed-out visitors. When a List timeline failed with 429, X staff asked first whether it loads in a browser signed in to X with ad and tracker blockers off, pointing to ERR_BLOCKED_BY_CLIENT lines in the console (an extension blocking requests). Privacy extensions and strict browser tracking protection commonly block platform.twitter.com or syndication.twitter.com, which leaves only your fallback link. Signed-out visitors also see different content by design: in an older forum thread on timeline ordering, X staff wrote that a logged-out user timeline returns a precomputed list of top posts rather than the latest posts in order, so "my newest post is missing" is often not a bug at all.
The two-minute check. Open the page, then DevTools, Network tab, and filter on timeline-profile (or timeline-list). A 429 with x-rate-limit-remaining: 0 is cause 1. A 200 followed by the hydrateRoot error in the Console is cause 2. No request, or ERR_BLOCKED_BY_CLIENT, is cause 3; confirm in a private window with extensions off. Also confirm the basics the earlier timeline section covers: the account is public, the anchor has class="twitter-timeline" and an x.com or twitter.com profile URL, and widgets.js is actually loaded once on the page.
The durable fix: render the timeline yourself. Fetch the account's latest posts on your server, cache them, and ship plain HTML, so no visitor ever calls syndication.twitter.com and no X script runs in their browser. The script below calls GET /twitter/user/last_tweets (newest first, 20 per page), caches the result for an hour, shows reposts under their original author, keeps the avatar, name and @handle linked to the profile with the text unaltered and the timestamp linked to the post (X's display requirements), and falls back to a plain link to the account if the fetch fails. We ran its rendering against the live response for @NASA; reads need no X account.
Cost. TwitterAPI.io bills 15 credits per post returned ($0.15 per 1,000 posts), so a full 20-post refresh costs $0.003 and an hourly refresh is 24 refreshes, at most $0.072 a day, however many visitors the page gets; an empty result costs the 15-credit minimum. For comparison, X's official API pay-per-use rate card lists $0.005 per post read, $5 per 1,000 posts, about 33x the per-post price. Credit packs are listed on the pricing page; new accounts that pass the automatic bot check get up to $1 of free credits (at most 100,000 credits, no card, one per person or network, expiring after 31 days).
# pip install requests
# Self-rendered profile timeline: the latest posts of one account as static HTML,
# cached on your server, so visitors never call syndication.twitter.com.
import html, json, os, time, requests

API_KEY = os.environ["TWITTERAPI_IO_KEY"]        # server-side only
CACHE = "timeline-cache.json"
TTL = 3600                                         # refresh at most hourly

def latest_posts(handle: str, limit: int = 10) -> list[dict]:
    if os.path.exists(CACHE) and time.time() - os.path.getmtime(CACHE) < TTL:
        return json.load(open(CACHE))[:limit]
    r = requests.get(
        "https://api.twitterapi.io/twitter/user/last_tweets",
        params={"userName": handle},               # newest first, up to 20 per page
        headers={"X-API-Key": API_KEY},
        timeout=20,
    )
    r.raise_for_status()
    body = r.json()
    if body.get("status") != "success":
        raise RuntimeError(body.get("msg"))
    tweets = (body.get("data") or {}).get("tweets", [])
    json.dump(tweets, open(CACHE, "w"))
    return tweets[:limit]

def render(tweets: list[dict], handle: str) -> str:
    items = []
    for t in tweets:
        t = t.get("retweeted_tweet") or t          # show a repost under its original author
        a = t["author"]
        items.append(f"""<li class="post">
  <a href="https://x.com/{a['userName']}"><img src="{html.escape(a['profilePicture'])}" alt="" width="40" height="40" loading="lazy">
  {html.escape(a['name'])} <span>@{a['userName']}</span></a>
  <p>{html.escape(t['text'])}</p>
  <a href="{t['url']}"><time>{html.escape(t['createdAt'])}</time></a>
</li>""")
    return (f'<ol class="x-timeline">{"".join(items)}</ol>\n'
            f'<a href="https://x.com/{handle}">View @{handle} on X</a>')

if __name__ == "__main__":
    handle = "XDevelopers"
    try:
        out = render(latest_posts(handle), handle)
    except Exception as e:                         # keep the page up: fall back to a link
        out = f'<a href="https://x.com/{handle}">View @{handle} on X</a>'
        print("fetch failed:", e)
    open("timeline.html", "w").write(out)
    print("wrote timeline.html")
# Cost: 15 credits per post returned; a full 20-post page = $0.003 per refresh.Which method should you use? Decision table + cost
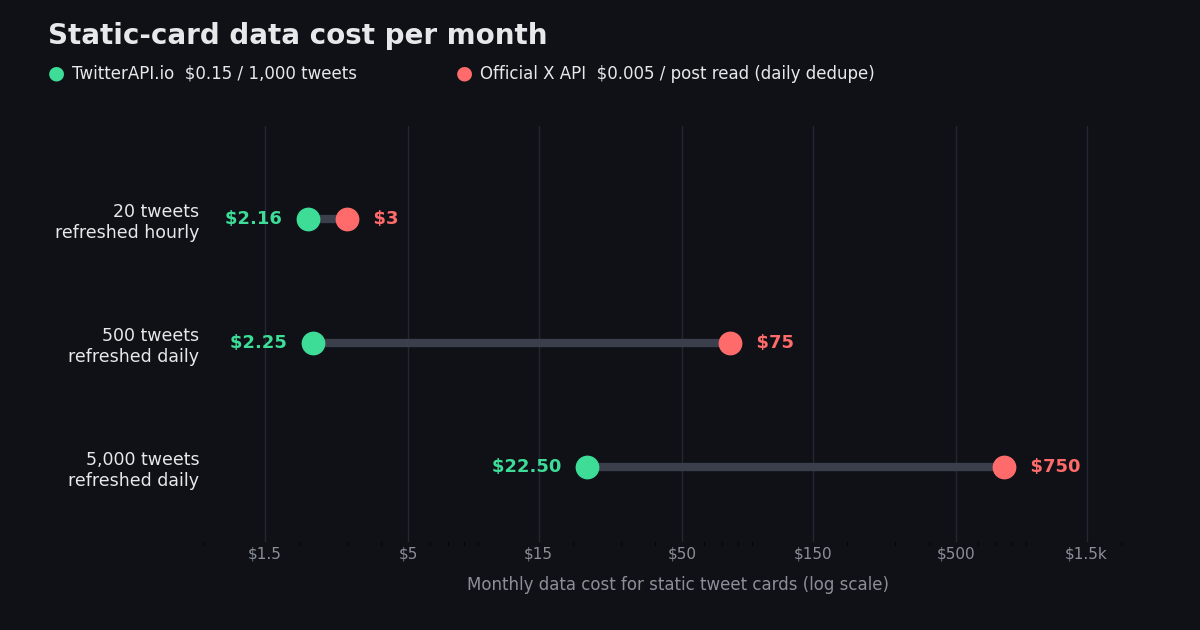
Cost of the data-driven methods. Copy-paste and oEmbed are free. Static cards need tweet data. On TwitterAPI.io that is $0.15 per 1,000 tweets returned (twitterapi.io/pricing), with a 15-credit ($0.00015) minimum when a request returns little or nothing. The official X API charges $0.005 per post read on its pay-per-use plan (docs.x.com pricing), deduplicated within a UTC day.
Per tweet returned, $0.005 ÷ $0.00015 ≈ 33× cheaper on TwitterAPI.io. Note the honest exception in the first row: because X dedupes repeat reads of the same post within a day, small sets refreshed many times a day cost about the same on both. The gap opens as the number of distinct tweets grows.
# 1) Free embed HTML for one tweet (no key). Cache the "html" field.
curl -s "https://publish.x.com/oembed?url=https://x.com/jack/status/20&omit_script=1&dnt=true"

# 2) Tweet data for static cards, many IDs per call (TwitterAPI.io key).
curl -s "https://api.twitterapi.io/twitter/tweets?tweet_ids=20,463440424141459456" \
  -H "X-API-Key: $TWITTERAPI_IO_KEY"
# -> {"tweets": [{"id": "20", "text": "just setting up my twttr", "author": {...},
#      "likeCount": ..., "retweetCount": ..., "createdAt": "..."}, ...], "status": "success"}
Researching this?Free starter credits cover end-to-end testing — Google sign-in, no card. Get a key.
Questions readers ask
How do I embed a tweet in HTML?
Open the tweet on x.com, click the share icon or three-dot menu, choose Embed post, and copy the snippet from publish.x.com. Paste it into your HTML. It is a <blockquote class="twitter-tweet"> plus a <script> tag that loads widgets.js, which converts the blockquote into a rendered tweet card.
Is the Twitter (X) oEmbed API free?
Yes. https://publish.x.com/oembed needs no API key or authentication and X's documentation lists it as not rate limited. It returns the embed HTML as JSON, with a cache_age of about 100 years, so cache the result instead of calling it on every page view.
Can I embed a tweet without an iframe or widgets.js?
Yes. Fetch the tweet's data (text, author, avatar, counts) on your server and render your own HTML card. React's react-tweet library does this, and you can do it in any stack with a tweet API such as TwitterAPI.io's /twitter/tweets endpoint. Follow X's display requirements: avatar, display name and @username linked to the profile, unaltered text, and the timestamp.
Why does my embedded tweet show only as plain text?
The blockquote is the fallback shown when widgets.js does not run. Common causes: an ad blocker or consent manager blocking platform.twitter.com, a Content-Security-Policy that does not allow that host, or a single-page app that added the blockquote after the script already scanned the page — call twttr.widgets.load() after inserting new content.
Can I embed a Twitter (X) feed on my website?
Yes, as a Profile or List timeline generated at publish.x.com (Likes, Collections and Moments timelines were retired in January 2023). Timelines load through X's logged-out syndication service, which can be unreliable, so for business-critical feeds fetch the latest posts server-side and render them yourself.
Do embedded tweets slow down my page?
Somewhat. In our measurement widgets.js is 27,731 bytes gzipped, and each embedded tweet then renders inside its own iframe, which adds requests and a layout shift when the card resizes. One embed is negligible; many embeds on one page are noticeable. Lazy-loading or static cards remove most of the cost.
Do embedded tweets update if the tweet is edited or deleted?
Embeds rendered by widgets.js are drawn by X at view time, so they reflect X's current copy of the post. The blockquote text you pasted, and any static card you built, is a snapshot from when you fetched it — refresh static cards on a schedule and remove cards for tweets that no longer return data.
Continue
- X Developer Platform — oEmbed API (parameters, no auth, cache_age)
- X for Websites — JavaScript API (createTweet, widgets.load)
- X for Websites — Embedded timelines (retired timeline types)
- X developer terms — display requirements for posts
- vercel/react-tweet — static tweet rendering for React
- oEmbed specification
- X API pay-per-use pricing (per post read)
- Twitter (X) API — cluster hub
- Twitter (X) API in Python — complete guide
- Every tweet metadata field explained
- Extract tweet image and media URLs
- Bulk-download Twitter (X) photos and videos
- TwitterAPI.io vs the official X API
- X API cost breakdown
- TwitterAPI.io pay-per-use pricing
- fxtwitter and FixupX: fix X link previews in Discord
- Twitter React: render tweets with react-tweet, widgets.js or the API
- 01PhantomBuster Pricing: Plans, Execution Hours and What X (Twitter) Data Really Costs
- 02Sprinklr Pricing: What It Costs Now That Self-Serve Has Ended
- 03Goose MCP: How to Add MCP Servers (Extensions) to goose, Desktop and CLI
- 04ChatGPT Apps SDK Tutorial: Build a ChatGPT App That Answers With Live Twitter (X) Data
- 05LM Studio MCP: Connect MCP Servers (and Live Twitter (X) Data) to a Local Model
- 06Most Liked Tweets of All Time
- 07Count Tweets — Twitter (X) API Programmatic Guide
- 08How to Search Tweets by Date via API — A Developer's Guide
Writing about something you built with TwitterAPI.io? Our community rewards program pays API credits for honest tutorials, build logs and videos.
Stop reading. Start building.
Starter credits cover real testing on real data. Google sign-in, no card, no application queue.
Get an API keyAlready building with TwitterAPI.io? Publish an honest tutorial or build log about it and earn up to $200 a month in API credits.