xcancel Not Working? The xcancel Alternatives That Still Work
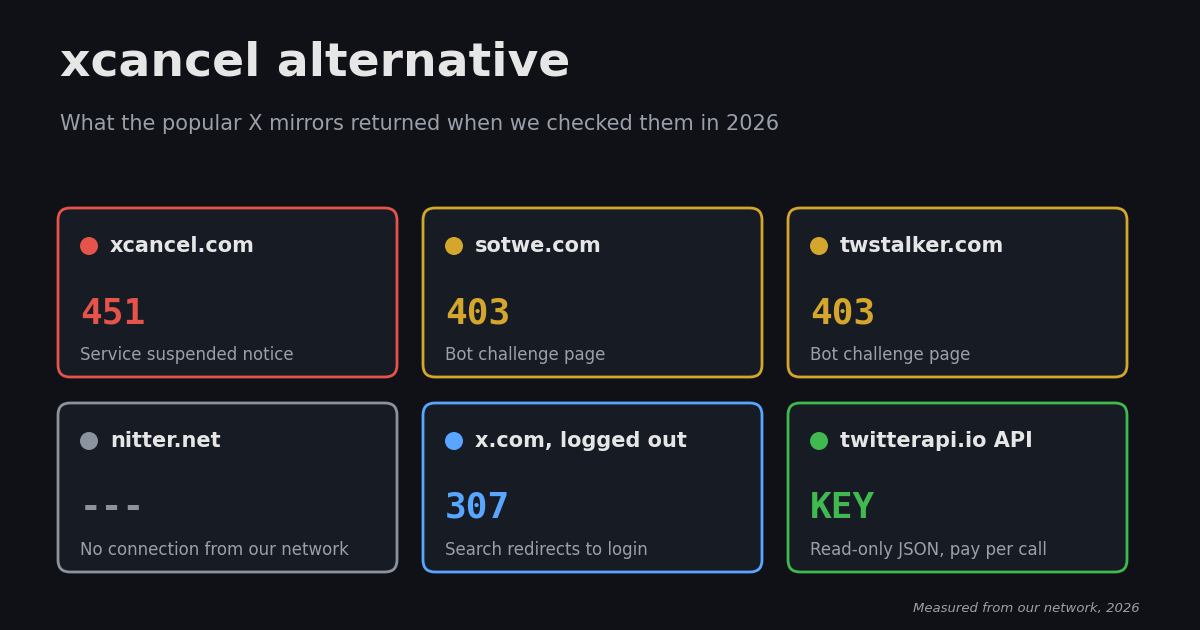
If you used xcancel.com to read X (Twitter) posts without an account, you probably landed here because the site now shows a black page that says the service is suspended. You are not alone, and nothing is wrong on your end. The same thing has been happening, with different symptoms, to sotwe.com, twstalker.com and most of the public Nitter instances that people swapped links to.
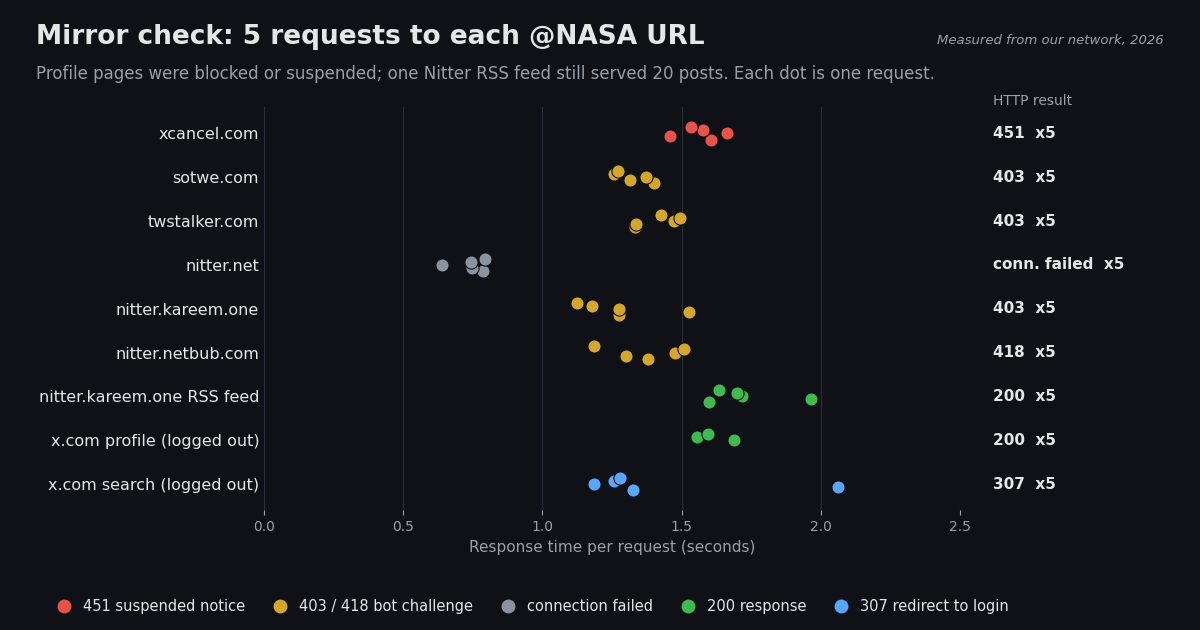
Rather than repeat old "top 10 Twitter viewers" lists, we checked each site ourselves in 2026: five requests per URL, recording the HTTP status, the response time, and whether any posts came back. The results are in the table and chart below, followed by the options that actually returned content and what each one costs you in privacy, effort, or money.
One note on scope: this page is for people who want to read public X posts. If you are a developer building a read-only viewer into your own product, the companion guide on the Twitter (X) viewer API goes deeper on that.
Why is xcancel not working?
xcancel.com was one of the most-linked instances of Nitter, the open-source, privacy-focused front end for X. You could swap x.com for xcancel.com in any link and read the post or profile without JavaScript, ads, or an account, and every profile had an RSS feed at /username/rss.
In our 2026 check, xcancel.com, a profile page (xcancel.com/NASA) and its RSS feed (xcancel.com/NASA/rss) all returned HTTP 451 on every attempt. 451 is the status code reserved for content unavailable for legal reasons. The page body reads: "Unfortunately, due to a new development in the ongoing legal proceedings, we are required to suspend this service again until further notice. We can't share more details." The word "again" matters: this is not the first time it went dark, so a quick return is not something to plan around.
The wider context comes from the Nitter project itself. Its GitHub README states that on 24 August 2026 X Corp. sent cease-and-desist letters demanding a permanent takedown of Nitter instances and of the project's repository, and adds that, following legal advice, the project will continue. The xcancel operator has not said whether its suspension is tied to the same letters, so treat that link as plausible, not confirmed.
Bottom line: if your bookmarks, browser redirect extension, or RSS reader point at xcancel.com, they will keep failing. Replace them with one of the options below.
We checked xcancel, sotwe, twstalker and Nitter: here are the results
Method: from our network in 2026 we sent five plain HTTP requests (a normal desktop Chrome user agent, no cookies, no JavaScript) to the @NASA profile on each site and recorded the status code, response time, and whether any posts came back. A plain HTTP client is exactly what RSS readers, link previewers, and scripts use, so this is the experience those tools get. A full browser can sometimes pass a bot challenge that a script cannot, and we flag that where it applies.
Two patterns stand out. First, the sites that are still alive have put bot checks in front of their pages. That protects their small pool of X sessions from scrapers, but it also breaks the RSS readers and link previews that made these mirrors useful. Second, feeds sometimes survive when pages do not: the RSS URL on one instance answered normally while its profile page was behind a challenge. We also tested the RSS feeds of three other listed instances: one returned 21 posts, one redirected, and one returned 403.
For context, the community-run nitter-status tracker (status.d420.de) listed seven public instances when we looked in 2026, five of them marked healthy and four with RSS enabled. Neither xcancel.com nor nitter.net was on that list. The tracker's own page asks people not to use the instances for scraping and to host Nitter themselves instead, which is a good hint about how fragile they are.
Why do xcancel, sotwe and twstalker keep breaking?
These sites are not caches of X. Every page they show is fetched from X at the moment you ask for it, so they inherit every limit X puts on that traffic. Four things break them, usually in combination.
1. They need real X accounts behind the scenes. Nitter was built to read X without signing in, but anonymous access is no longer enough: the Nitter wiki now states plainly that "Nitter requires real accounts to authenticate API requests". Instance operators load session cookies from real X accounts into a sessions.jsonl file. When X locks or suspends those accounts, the instance goes blank.
2. Each account has a rate limit. A public instance serving thousands of readers spreads the load over a pool of accounts. The Nitter README warns that running a large public instance "is not feasible with a small amount of accounts". When traffic outgrows the pool, you see errors, empty timelines, or a queue page (one listed instance showed a "Nitter Access Queue" page in our check).
3. Scrapers abuse them. Free, unauthenticated access to X data attracts bots. The Nitter README notes that RSS feeds are "often disabled due to abuse", and the bot challenges we hit on sotwe, twstalker and two Nitter instances are the operators' defense against that load.
4. Legal pressure. xcancel's own notice cites ongoing legal proceedings, and the Nitter README records the cease-and-desist letters from X Corp. A site can be technically healthy and still disappear overnight.
What this means for you: any free mirror is a moving target. It is fine for occasionally opening a link someone sent you. It is a poor foundation for anything you rely on, such as a daily RSS digest, a research log, or a monitoring workflow.
The xcancel alternatives compared
Here is every realistic option side by side. "Works now" comes from our 2026 checks above; anything we could not confirm is marked as such rather than guessed.
A few rows need a word of explanation. sotwe and twstalker are not Nitter instances; they are independent viewer sites. We could not get past their bot challenge with a plain HTTP client, so we can't vouch for what they show in a browser today. They are also third-party sites with ads and trackers, so they don't offer the privacy that drew people to xcancel. Logged-out x.com is the free option nobody can take away, but it is limited: individual post links and profiles open, while search sent us to the login screen on all five tries.
Which xcancel alternative should you use?
You just want to open a post someone linked. Open the original x.com link. Logged-out viewing of individual posts and profiles still works, and it is the only option that cannot be suspended. Use a private window if you don't want it tied to an existing session.
You read a few accounts and care about privacy. Try a currently healthy public Nitter instance from the nitter-status tracker, and expect to swap instances from time to time. Its RSS feeds are the most durable part; in our check a feed kept working while the same instance's profile page sat behind a bot challenge.
You want your old xcancel RSS feeds back for good. Either self-host Nitter (you will need one or more real X accounts and some Linux comfort; the project wiki walks through creating session tokens) or generate the feeds yourself from an API, as in the script at the end of this page.
You need search, many accounts, or anything automated. Mirrors are the wrong tool. A read-only data API returns the same public posts as structured JSON, without an X account that can be locked and without depending on someone else's instance staying online.
You read X every day anyway. Honestly, a regular X account with Lists is the least hassle. The cost is privacy: your reading is tied to an account, which is exactly what xcancel let people avoid.
Read X posts through an API instead of a mirror
Under the hood, xcancel did one thing: it asked X for a profile and its latest posts and rendered them as a simple page. You can do the same with two read-only calls to twitterapi.io, with no X account and no session tokens to maintain. GET /twitter/user/info returns the profile card (name, bio, followers, following), and GET /twitter/user/last_tweets returns the newest posts, up to 20 per page, each with text, createdAt, likeCount, retweetCount and a url back to the original post.
The script below prints a profile and its latest posts in the terminal, which is the xcancel experience minus the browser. Set TWITTERAPI_IO_KEY to a key from your dashboard first.
Two practical notes from the API docs. Results are paginated at up to 20 posts, so pass the returned cursor to read further back. And if you want to watch one account for new posts every few seconds, polling last_tweets is the expensive way to do it; the docs point to the real-time monitoring options for that case.
import os
import requests

API_KEY = os.environ["TWITTERAPI_IO_KEY"]  # from twitterapi.io/dashboard
HEADERS = {"X-API-Key": API_KEY}


def get_tweets(body):
    # The tweet list can sit at the top level or under "data"; handle both.
    if isinstance(body.get("tweets"), list):
        return body["tweets"]
    return (body.get("data") or {}).get("tweets", [])


def view_profile(username):
    # 1) Profile card: name, bio, follower counts
    r = requests.get(
        "https://api.twitterapi.io/twitter/user/info",
        params={"userName": username},
        headers=HEADERS,
        timeout=30,
    )
    r.raise_for_status()
    user = r.json().get("data") or {}
    print(f"{user.get('name')} (@{user.get('userName')})")
    print(f"{user.get('followers')} followers, {user.get('following')} following")
    print((user.get("description") or "").strip())
    print("-" * 60)

    # 2) Latest posts, newest first (up to 20 per page)
    r = requests.get(
        "https://api.twitterapi.io/twitter/user/last_tweets",
        params={"userName": username, "includeReplies": "false"},
        headers=HEADERS,
        timeout=30,
    )
    r.raise_for_status()
    for t in get_tweets(r.json()):
        text = (t.get("text") or "").replace("\n", " ")
        print(f"[{t.get('createdAt')}] {text[:140]}")
        print(f"   likes {t.get('likeCount')}  reposts {t.get('retweetCount')}  {t.get('url')}")


if __name__ == "__main__":
    view_profile("NASA")
Search X without logging in
Search is the feature logged-out x.com no longer gives you (it redirected us to the login page on every attempt) and the first thing to break on overloaded Nitter instances. GET /twitter/tweet/advanced_search accepts the same query syntax you would type into X search, such as from:, since:, min_faves:, lang: and quoted phrases, plus queryType set to Latest or Top. Each page returns about 20 posts, with has_next_page and next_cursor for paging.
If you just need to look up a few searches by hand, the Twitter advanced search guide linked at the end of this page covers the operators in detail.
import os
import requests

HEADERS = {"X-API-Key": os.environ["TWITTERAPI_IO_KEY"]}

# Same operators you would type into X search: from:, since:, min_faves:, lang:, "exact phrase"
r = requests.get(
    "https://api.twitterapi.io/twitter/tweet/advanced_search",
    params={"query": "from:NASA artemis", "queryType": "Latest"},
    headers=HEADERS,
    timeout=30,
)
r.raise_for_status()
body = r.json()
for t in body.get("tweets", []):
    print(t.get("createdAt"), "|", (t.get("text") or "")[:120])

# Roughly 20 results per page; pass body["next_cursor"] as "cursor" for the next page
print("more pages:", body.get("has_next_page"))
What does it cost compared with the official X API?
A mirror is free until it disappears. If you move to an API, it helps to know the actual bill. Here is the cost of one "xcancel-style" check, meaning one profile plus its 20 latest posts, using each provider's published per-unit prices.
Prices come from the twitterapi.io pricing page and the official pay-per-usage pricing page on docs.x.com, both checked in 2026. The ratio works out to roughly 34x ($0.11 / $0.0032). twitterapi.io also has a minimum charge of $0.00015 per call, which only matters when a call returns very few items. These figures assume a full page of 20 posts; quieter accounts return fewer and cost less.
"""Rebuild the "Nitter RSS feed" you lost when xcancel went down.

Writes one RSS 2.0 file per account. Point any feed reader that accepts local
files (or a static file host) at the output. Run it on a schedule, e.g. hourly cron.
"""
import os
import requests
from email.utils import format_datetime
from datetime import datetime
from xml.sax.saxutils import escape

HEADERS = {"X-API-Key": os.environ["TWITTERAPI_IO_KEY"]}
ACCOUNTS = ["NASA", "nasawebb"]          # handles you used to read on xcancel
OUT_DIR = "feeds"


def latest_tweets(username):
    r = requests.get(
        "https://api.twitterapi.io/twitter/user/last_tweets",
        params={"userName": username, "includeReplies": "false"},
        headers=HEADERS,
        timeout=30,
    )
    r.raise_for_status()
    body = r.json()
    if isinstance(body.get("tweets"), list):
        return body["tweets"]
    return (body.get("data") or {}).get("tweets", [])


def to_rfc822(created_at):
    # createdAt uses the classic X format: weekday month day HH:MM:SS +0000 year
    try:
        return format_datetime(datetime.strptime(created_at, "%a %b %d %H:%M:%S %z %Y"))
    except (TypeError, ValueError):
        return ""


def build_feed(username, tweets):
    items = []
    for t in tweets:
        link = t.get("url") or f"https://x.com/{username}/status/{t.get('id')}"
        text = t.get("text") or ""
        items.append(
            "<item>"
            f"<title>{escape(text[:90])}</title>"
            f"<link>{escape(link)}</link>"
            f"<guid isPermaLink=\"true\">{escape(link)}</guid>"
            f"<pubDate>{to_rfc822(t.get('createdAt'))}</pubDate>"
            f"<description>{escape(text)}</description>"
            "</item>"
        )
    return (
        '<?xml version="1.0" encoding="UTF-8"?>'
        '<rss version="2.0"><channel>'
        f"<title>@{escape(username)} on X</title>"
        f"<link>https://x.com/{escape(username)}</link>"
        f"<description>Latest posts from @{escape(username)}</description>"
        + "".join(items)
        + "</channel></rss>"
    )


if __name__ == "__main__":
    os.makedirs(OUT_DIR, exist_ok=True)
    for handle in ACCOUNTS:
        tweets = latest_tweets(handle)
        path = os.path.join(OUT_DIR, f"{handle}.xml")
        with open(path, "w", encoding="utf-8") as f:
            f.write(build_feed(handle, tweets))
        print(f"wrote {len(tweets)} items to {path}")
Questions readers ask
Is xcancel down permanently?
Nobody outside the operator knows. In our 2026 check every xcancel.com URL returned HTTP 451 with a notice that the service is suspended "until further notice" because of a development in ongoing legal proceedings, and the notice says it is suspending "again". Plan as if it will not come back soon.
Why does xcancel show error 451?
HTTP 451 means content is unavailable for legal reasons. xcancel's own notice says the suspension follows "a new development in the ongoing legal proceedings" and that it can't share more details. The Nitter project, which xcancel ran on, separately reports that X Corp. sent cease-and-desist letters to Nitter instances on 24 August 2026.
Is sotwe still working?
Not for scripts or feed readers. sotwe.com redirects to www.sotwe.com, which answered all five of our scripted requests with a 403 "Just a moment..." bot-challenge page. A full browser may get through that challenge, so it may still load for some visitors, but we could not confirm what it shows.
What happened to twstalker?
twstalker.com behaved like sotwe in our 2026 check: every scripted request got a 403 bot-challenge page instead of a profile. It is an independent viewer site, not a Nitter instance, so the Nitter instance lists and status trackers don't cover it.
Can I still view X (Twitter) without an account?
Partly. Logged-out x.com still loads individual posts and profile pages, but search redirected us to the login screen on every attempt. For search or RSS without an account, your options are a working public Nitter instance, a self-hosted Nitter (which itself needs X account sessions), or a read-only API that only needs an API key.
Is there a Nitter instance that still works?
Some do, but the list changes often. When we looked in 2026, the nitter-status tracker at status.d420.de listed seven public instances with five marked healthy. Check the tracker right before you switch, keep a second instance as a backup, and note that several instances now put a bot check in front of their pages.
How do I get my xcancel RSS feeds back?
Three routes. Swap the domain in your feed URLs to a healthy Nitter instance that has RSS enabled (one we tested returned 20 posts on every request). Self-host Nitter with your own X account sessions. Or generate the feeds yourself from an API; the script at the end of this page writes one RSS file per account from twitterapi.io's last_tweets endpoint.
Is using xcancel or Nitter private?
More private than x.com: Nitter fetches everything server-side, so X sees the instance, not your IP address or browser fingerprint, according to the Nitter README. You are trusting the instance operator instead. sotwe and twstalker are different: they are ad-supported third-party sites and don't make the same promise.
Continue
- Nitter on GitHub: project README, including the cease-and-desist notice and RSS abuse note
- Nitter wiki: why instances need real X account sessions
- Nitter wiki: community-maintained instance list
- nitter-status: third-party uptime tracker for public Nitter instances
- X API pay-per-usage pricing (docs.x.com), the official alternative
- twitterapi.io docs: Get User Last Tweets endpoint
- Twitter (X) API overview: the hub for reading X data
- Twitter (X) viewer API: build a read-only viewer
- Scrape Twitter (X) without the official API
- Twitter advanced search operators guide
- Monitor X accounts for new tweets in real time
- twitterapi.io pay-per-call pricing
Stop reading. Start building.
Starter credits cover real testing on real data. Google sign-in, no card, no application queue.
Get an API key